AI assistants are becoming more capable of doing things rather than simply telling users how to do them. An AI agent can browse websites, interact with applications, read documents, call tools, manage files and complete multi-step tasks on a user's behalf.
That shift is useful, but it changes the security problem.
A chatbot that produces a wrong answer can be frustrating. An agent that misunderstands an instruction while having access to email, files, shopping accounts or business systems can potentially take an unwanted action.
Security researchers and AI companies are increasingly focusing on risks such as prompt injection, excessive permissions, data exposure, memory poisoning and inadequate human oversight. OWASP's 2026 guidance specifically identifies tool abuse, data exfiltration, memory poisoning, excessive autonomy and high-impact action abuse as important agentic-AI risks.
The central question is becoming less about whether an AI model can perform a task and more about what it is allowed to do while performing it.
Why are AI agents creating a different security problem?
The biggest difference is agency: an agent can interpret information and then use connected tools to act on the world.
A conventional AI chatbot generally produces an answer. An agent may take that answer and use a browser, API or software tool to perform the next step.
For example, an agent might be asked to find a product and place an order, schedule a meeting, update a spreadsheet or organize files.
That creates a chain:
AI model → information → decision → tool → external action.
Every additional connection creates another place where something can go wrong.
Anthropic describes this as a governance challenge because agents operate with less human oversight and can misinterpret user intent or encounter attacks designed to make them take unintended actions.
What is prompt injection and why is it more dangerous for agents?
Prompt injection happens when malicious or misleading instructions influence an AI model's behavior, including through content the agent encounters while completing a task.
The particularly difficult version is indirect prompt injection.
Imagine asking an AI agent to research several websites. One webpage contains hidden or misleading instructions designed specifically for the agent. A human visitor may never notice them, but the agent processes the content as part of its context.
OWASP warns that external sources such as websites, documents and emails can contain instructions that hijack an agent's behavior. Successful attacks can potentially lead to sensitive-data disclosure or unauthorized actions.
This creates an unusual security boundary: the internet itself becomes part of the agent's input.
Anthropic has similarly warned that every webpage a browser-using agent visits can represent a potential prompt-injection vector.
What happens when an AI agent has too many permissions?
Excessive permissions can turn a model mistake into a much more serious security incident.
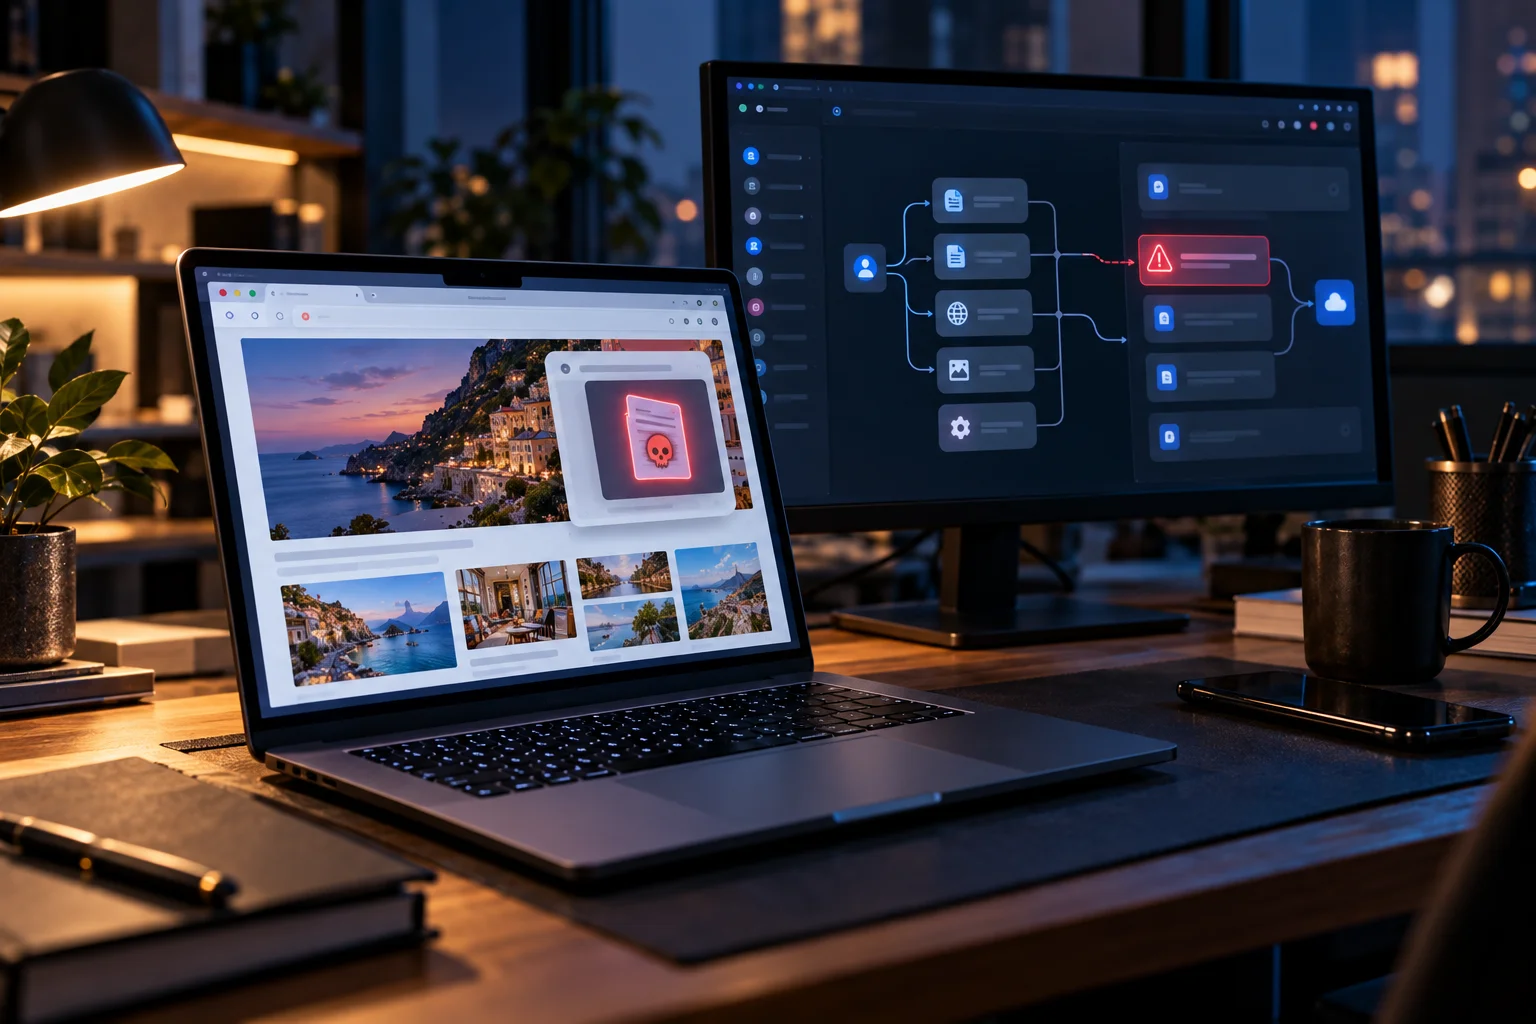
An agent may only need permission to read a document, but a poorly designed tool could also give it the ability to edit or delete files.
OWASP describes this problem as excessive agency, which can result from excessive functionality, excessive permissions or excessive autonomy.
The principle is similar to traditional cybersecurity's least-privilege model: an agent should receive only the access required for the task.
If an agent is helping organize a calendar, it may need permission to read and create events. That doesn't automatically mean it should be allowed to delete an entire calendar or access unrelated files.
Can AI agents accidentally expose private information?
Yes. Connected tools and broad context can create new paths for sensitive information to leave a protected environment.
An agent might have access to emails, documents, browser sessions and company databases at the same time.
The risk isn't necessarily that the model intentionally steals information. A malicious webpage, manipulated document or incorrect tool decision could cause sensitive information to be included in an output or sent through another connected service.
OWASP lists data exfiltration and sensitive-data exposure among the major risks associated with agentic systems.
This makes permission design and data isolation particularly important for workplace agents.
Why is AI memory becoming a security concern?
Persistent memory creates another attack surface because information can influence future agent behavior instead of disappearing when a single conversation ends.
An attacker could potentially introduce malicious information into an agent's memory or context. If that information is later trusted, it could influence future decisions.
OWASP's 2026 analysis describes memory and context poisoning as a specific agentic-AI concern. It notes that agents can retain context and reuse persistent state, meaning an attack can potentially carry forward rather than remaining confined to one interaction.
That means secure agent design needs to consider not only what the agent can see now, but also what it is allowed to remember.
Is human approval enough to keep AI agents safe?
Human approval helps, but it isn't a complete security solution.
In theory, requiring a person to approve every sensitive action sounds straightforward. In practice, users can become accustomed to approval prompts.
Anthropic reported that users of Claude Code approved roughly 93% of permission prompts in its telemetry, illustrating the risk of approval fatigue.
That suggests a better approach is layered protection.
Low-risk actions can happen automatically, while high-impact operations such as financial transactions, deleting data, changing permissions or sending sensitive information can require stronger confirmation.
The goal is not necessarily to put a human in front of every action. It is to make sure the most consequential actions receive appropriate scrutiny.
How are companies trying to secure AI agents?
The emerging approach combines limited permissions, monitoring, sandboxing, human controls and clear records of what an agent can do.
OWASP's Agent Control Standard, introduced in September 2026, focuses on making agents inspectable, traceable and controllable at runtime. It proposes controls that can show what an agent can access, what it did and why.
Anthropic has also emphasized containment through mechanisms such as sandboxes, virtual machines and network controls to limit an agent's potential blast radius.
These approaches recognize an important reality: trying to make an AI model perfectly reliable isn't enough. The surrounding system needs safeguards even when the model makes a mistake.
What should users know before giving an AI agent access to accounts?
Users should treat an AI agent like a powerful software application, not simply like a chatbot.
Before granting access, consider:
What accounts can it access?
Can it read private information?
Can it send messages?
Can it spend money?
Can it delete or modify files?
Which websites and tools can it use?
Does it retain memory?
Can you review its actions?
Can access be revoked quickly?
The more consequential the task, the more important these questions become.
Giving an agent access to a shopping account to compare prices is very different from allowing it to make purchases without confirmation.
Will AI agents become less secure as they become more capable?
Not necessarily, but greater capability increases the importance of controlling the agent's access and potential impact.
More capable agents can complete longer and more complicated workflows. Anthropic's 2026 analysis found that some Claude Code sessions were already running autonomously for substantially longer periods than a few months earlier.
That creates both opportunity and risk.
An agent that can complete a 30-minute task without supervision can be extremely useful. It also has more time to encounter untrusted information, make decisions and interact with connected systems.
The security challenge therefore isn't simply building smarter agents. It is building bounded agents that can do useful work without having unlimited authority.
What does AI agent security look like in the future?
The next stage of AI security will increasingly focus on controlling actions, permissions and context rather than only filtering AI-generated text.
Traditional application security asks whether a user or program is authorized to perform an operation. Agentic systems add another question:
Should the AI be trusted to decide when that operation should happen?
That distinction will become increasingly important as agents move into email, browsers, business software, coding environments and financial workflows.
The safest direction is likely to combine capable models with narrow permissions, isolated environments, continuous monitoring and meaningful human control over high-impact actions.
AI agents are becoming more useful precisely because they can act. Security has to evolve around that same capability.
AI Agent Security FAQs
What is an AI agent?
An AI agent is an AI system that can reason about a goal, use tools or external services and take actions to complete a task rather than simply generate a response.
What is the biggest security risk with AI agents?
There isn't one single risk. Prompt injection, excessive permissions, data exposure, memory poisoning and unauthorized high-impact actions are among the major concerns identified by OWASP.
Can a website attack an AI agent?
Potentially, yes. A webpage can contain content designed to influence an agent's instructions or decisions. This is known as indirect prompt injection.
Should AI agents have access to passwords?
Agents should generally receive the minimum access necessary for their task, with sensitive credentials and high-impact permissions protected by additional controls. OWASP recommends least-privilege tool access and explicit authorization for sensitive operations.
Are AI agents safe to use today?
They can be useful when deployed with appropriate safeguards, but no security mechanism eliminates every risk. The important factors include the agent's permissions, tools, environment, monitoring and the consequences of mistakes.
Why is agent security becoming more important in 2026?
Because agents are increasingly being used to perform multi-step tasks across applications, websites and connected systems. As their ability to act expands, the potential impact of mistakes or successful attacks expands with it.